Click a paragraph to jump to that point in the audio.
Julia: [00:00:00] I did not know you could run out of iNodes, and I was like, I will tell the world that you can run out of iNodes.
Bridget: It’s time for Arrested DevOps, the podcast where we help you achieve understanding, develop good practices, and operate your team and organization for maximum DevOps awesomeness. I’m Bridget, and today I’m chatting with Julia Evans. The show notes for this episode can be found at arresteddevops.com/discovery. But first, a word from our sponsors. Arrested DevOps is brought to you by Tenth Magnitude, a company that figures if you’re listening to this podcast, you must be pretty cool. Tenth Magnitude empowers businesses to better collaborate across teams and achieve IT transformation using cloud. They enable customers to innovate, automate, and accelerate by leveraging the power of Microsoft Azure. You can find out more at arresteddevops.com/tenthmagnitude. This episode is also brought to you by Hired. Hired is a platform for top developer jobs, and they love DevOps people. Developers get an average of 5 to 10 offers on the platform, all with just one application. You get job offers and salary or equity upfront before you interview, so you don’t have to waste your time interviewing for jobs you might not want. And they work with over 4,000 companies from startups to large public companies all over the place. ADO listeners get double the $2,000 bonus just for signing up at arrestedevops.com/hired.
[00:01:25] This episode is sponsored by VictorOps, the company that makes being on call suck less. Built by a team of avid DevOps practitioners, VictorOps is the most innovative platform available to support modern IT and DevOps incident management. They do it with an unmatched feature set that’s designed to support teams through the entire incident lifecycle, from first alert to final retrospective. This means you can respond to incidents more effectively, which in turn helps you release faster, minimize downtime, and get your life back. Visit arresteddevops.com/victorops to schedule a demo or start your trial. Mention Arrested DevOps, and you’ll be eligible for some great discounts too. I’m so excited to be chatting with Julia today. All right, so our topic, like, the broader topic today is discovery. And we’re going to talk about specific and general discovery, because I think of everyone I know, Julia is, like, the most excited about learning, which is Really delightful. She writes zines, actual paper zines, and awesome blog posts about interesting tech stuff. So, we’ll get into that. But first, Julia, tell our listeners about yourself.
Julia: [00:02:32] I’m Julia. I work as a software developer at Stripe, where I work on— what do I work on? Oh, so, we have all these AWS instances, and I try to work on making programs run on them.
Bridget: Well, that is, that is in fact a thing that people do.
Julia: And making it easier to use for like our developers. Um, and then in my spare time, like you mentioned, I spend a lot of time like writing this blog where I’m like, hello, I learned what a container is today. Um, or, okay, now that I learned what a container is 6 months ago, here are 1 bajillion more things I have learned about containers since then.
Bridget: Um, there are at least a bajillion things, possibly 2 bajillion.
Julia: Possibly 2 bajillion. Um, nice.
Bridget: Okay, cool. So like, I guess in terms of since you haven’t been on our show before, like the main thing that I think our listeners are always excited about or interested in is like, hey, they have a cool guest on. Um, what do, uh, what What are they the most excited about right now? Like, what have they been learning? And you mentioned containers, but what other interesting stuff have you learned lately?
Julia: [00:03:54] So, yesterday, I’ve been trying to understand what’s up with distributed systems.
Bridget: Just a small topic.
Julia: Yeah. Like, what’s the deal, right? And, like, you have this, like, trade-off between consistency and availability. And I’ve been trying to understand, like, how to think about that. And really, like, really how to think about it, like, when you have, like, a real system in your life that you’re dealing with, right? And you’re like, okay, how does this, like, theoretical trade-off and these theorems apply to, like, my real system that I have in front of me?
Bridget: Right, because you work at Stripe, and as I understand it, Stripe does money things. Like, people care a lot about your consistency and your availability.
Julia: That’s right. Yeah. Yeah. So, we spend a lot of time having conversations about, like, this system, Is it okay if it’s not? Because some systems, especially the less money systems, are okay to be a little less consistent, right? Depending on what they’re doing. And also, we want every system to be as available as possible.
Bridget: [00:04:57] As one does.
Julia: As one does.
Bridget: Yeah. Nice. So I feel like there’s so many questions, so many places to start, I guess. For our listeners who may not be super familiar with CAP theorem, do you want to just kind of give a quick overview of what that is? We’ve touched on it and we’ve touched on it a little in the past. We had Kyle Kingsbury on at one point, but we can’t assume everyone listened to that episode.
Julia: So yeah, for sure. And I think it took me a really long time to understand what was happening. Like, like I would read the definition and I like, I have a math degree, so I was like, I should understand this. This is a theorem. Like, I know all about theorems. But then translating it into real life has been really hard. So the deal with the CAP theorem is you have a system, or the way I think about it is you have a system and there are a few different properties it could have. One of them is that it could be strongly consistent, which is kind of a weird thing. Like, what does that even mean? Right? And so there’s this— what is it? So what people mean by this is something called linearizable. And I actually always forget the definition of that. I can’t hold it in my head for more than 2 hours. You probably know what it means.
Bridget: [00:06:15] I don’t know. Something that you can put in a line.
Julia: Yeah, it’s like you can put everything in a line. So when you write something, if you write a to, you definitely want— yeah, I think it means that you can put all of the actions that happen in the system on a line. Yeah. Right. Um, which is actually like a very strong property, um, because like it could be that you’re like, well, this happened after this, but like it could have been that it was like 1, 2, 3 or 1, 3, 2 and like no big deal, doesn’t really matter. But sometimes it does really matter and you do really care about the order, right? Um, so this is this property of being linearizable, um, which is something that a lot of database people want. Um, and then there’s also the property of being like available, which means that people can actually use your database. And it turns out the pieces of blocks are in contention and you cannot actually have a database which is always like, gives you like linearizable reads and writes. And that is also always available because there are network partitions and sometimes your network will be down and like the different computers. Oh, I mean, you can, yeah. And then the different computers are like, what’s happening? I can’t talk to anyone. I don’t know what’s going on. I’m just gonna panic.
Bridget: [00:07:30] Well, and that’s, um, so Katie McCaffrey from, uh, Twitter has talked a lot about, um, CAP theorem, and she likes to say that that P, um, that you mentioned, partition tolerance, like, you don’t get to choose to just not have partitions because there’s like physics and math and reality that means that your distributed systems are probably not going to be able to talk— every piece able to talk to every other piece at the same time.
Julia: That’s right. Yeah. So I think we’ve done a good job of being like, you can’t— I like— Koda Hale also has a post about this called, like, you can’t sacrifice predictive tolerance. And it’s like, well, we all live in the real world. And in the real world, and it just, it isn’t just about network partitions, right? Which I think Kyle has talked about a lot. He’s been like, well, you have garbage collection pauses, right? Where you have like a Java application and it decides, Sorry, you’re not getting a reply because I’m garbage collecting for the next minute.
Bridget: Oh, I remember there’s, like, an amazing one from when I used to run HBase clusters, and it’s called the Juliet pause. And it’s, like, it’s so romantic sounding and yet tragic because it’s basically the system thinks that the other part is dead, and so it just kills itself.
Julia: [00:08:42] I’ve been thinking about that, and I ran into Martin Kleppmann at Strangeloop. And he’s like super nice. And I was like, I don’t really understand, like, what’s up with the cap theorem, man? Like, I feel confused. And he’s like— and he was like, you shouldn’t pay attention to the cap theorem. Like, it’s true, but like there are more interesting things you can say. And I was like, what? What are you talking about? So, so wait, what are these more—
Bridget: what are these more interesting things?
Julia: What are the more interesting things? Exactly. So he has this paper called A Critique of the CAP Theorem, which I read last night. Strange Loop was like in September, so it’s like about time to like actually like read the things that I said I was going to read after. So I read this paper last night and he has like various critiques, which I’m not going to go into. But the more useful thing is like he has a proposal for a different way to think about systems, which is let’s say you have a network and the network has some delays in it.
Bridget: [00:09:46] Right?
Julia: Like 20 seconds or something, right? Like it takes 20 seconds for one computer to talk to another. Different algorithms, right, for like distributing information need to talk to each other like different amounts of times, right? So if you have like a linearizable system, then the computers need to talk to each other a lot. And if you have a system which is just like, lol, I don’t care, I’ll just give you whatever I have, then the computers don’t need to talk to each other at all. Right? Sure. So he kind of expresses, he says, okay, if the network is slow for a linearizable system, your reads are slow and your writes are slow. And then he uses big O notation, but basically he’s saying your reads and your writes are both slow. But then there’s this other level of consistency called causal consistency, which I still don’t understand what it means. But in that model, which is much weaker, then your reads and writes are both fast. You can have instant reads and instant writes even if the network is sad. And then there’s like—
Bridget: [00:10:47] I’m suspicious, like, #OpsLife, I’m immediately suspicious of those writes. Like, are these YOLO writes? We kind of hope, but sure.
Julia: Yeah, right. Yeah, yeah, exactly. Like, you obviously have less good guarantees if your writes are fast, right? And then there’s some intermediate model. Where your writes are slow but your reads are fast. And so talking about the speed of your reads and writes in the case of a slow network feels like it’s a more— how do you say? It’s a bit of a richer model than just the CAP theorem, which only addresses 2 scenarios, right?
Bridget: Yeah, it’s more nuanced.
Julia: Yeah, it’s more nuanced. And I feel like it— but it’s also not that complicated of a model, right? Um, and you’re just like, well, what happens when your network gets slow? And like, that’s like, feels easy for me to think about intuitively.
Bridget: Yeah. Um, yeah, so this, it, that sounds like a cool paper. So we’ll have to, I believe you have a link to it that you’ll be, uh, I do, we’ll be putting in the show, we’ll be putting that in the show notes. Um, okay, so this is a paper that you read because of some conversation you had at Strangeloop. I feel like that seems like a long way to go for some people who you know, maybe you feel like papers aren’t for them or didn’t go to Strange Loop. Like, how do you find stuff that you want to learn and how do you recommend people find interesting stuff?
Julia: [00:12:07] So I basically don’t read papers.
Bridget: Like, Papers We Love crowd will be so sad.
Julia: I love the Papers We Love crowd. I go to Papers We Love in Montreal, but I never read the paper. I just go and I listen to what the person has to say and then I always learn something. And then I ask really dumb questions which would have mostly been resolved by reading the paper.
Bridget: I don’t feel like you’re expected to read the paper before the presentation. At least I hope you’re not.
Julia: Yeah, I hope not because I never have. Um, yeah, I mean, I don’t read it after the paper.
Bridget: I don’t really read it after the presentation.
Julia: I read a huge number of papers because I probably read like 4 this year. And I mostly read papers when someone prints out a paper and hands me a physical copy of it.
Bridget: Um, wow.
Julia: And it’s like, Julia, this paper is for you. And then I’ll like maybe sometimes go home and read it.
Bridget: That sounds like the kind of thing that you would read in that exciting 10,000 feet after takeoff, but before you get to the level of the airplane where you can use the Wi-Fi. I feel like the paper would be good for that. So, when you’re finding which stuff you wanna learn about, like, what motivates you to say, this is something I wanna dig into?
Julia: [00:13:16] I have a lot of feelings that I don’t understand things. Like, so, for, like, distributed systems is one of those things where, like, I think it often starts as just like a feeling of discomfort around a topic where I’m like, I don’t really get what’s happening here with this CAP theorem. Right. And I think often that kind of discomfort is not resolved by— someone will be like, oh, you should read the definition. And I’m like, well, I read the definition, but that did not resolve all of my discomfort around—
Bridget: sometimes it makes it worse.
Julia: Yeah, sometimes it makes it worse. Right.
Bridget: You’re like, I know all of those words separately.
Julia: Yeah, I’ll be like, I got all the words, but I still don’t really understand what’s happening. So I spend a lot of time kind of being uncomfortable with how well I understand something and then trying to understand why I feel uncomfortable. And I’m like, well, why is this confusing? And then with the CAP theorem, it could be because actually I have systems which are not well described by this theorem, right? Because it’s only about linearizability. And if I have systems that aren’t trying to be linearizable, then it’s like not really the best model, right? So then the problem might not be that I don’t understand the CAP theorem, but that the CAP theorem is not the answer to my questions.
Bridget: [00:14:33] And then that’s, that’s a subtle but important point, because I think a lot of times in tech people are looking for answers. And especially when you’re trying to solve specific problems in the workplace, it’s very tempting to jump for something that looks like an answer. It might not be the answer or a complete answer or any sort of answer at all to your problem, but things that sound like an answer are very compelling. That brings us actually, that segues nicely into, you just wrote a really interesting blog post about service discovery at Stripe. I want to dig into that a little bit, and we’re going to have a link to it in the show notes. But this covers a lot of these areas because it’s not— I think probably a lot of people don’t sit around at home going, service discovery, I wish I knew more about that. Like, you had a reason. And a lot of people also don’t make technical decisions, you know. Charity Majors likes to talk about good technical decision-making. And a lot of it doesn’t come down to, like, I heard about Tool Foo, it’s awesome, we should use that in production now. So, can you talk a little bit about, just, I mean, you don’t have to go step by step through the blog post, but you can talk a little bit about how service discovery at Stripe got started, why, wherefore, what?
Julia: [00:15:53] Yeah. So, the reason I wrote this blog post, well, there are a few reasons. One reason was that I’m on the team that owns service discovery at Stripe. I did not set up the system. And so like at the beginning, like when I joined this team, I didn’t know like very much about how it worked. I was like, we have this service discovery system. It’s like real important. I should know how this works, right? And I was like, and then at some point I gave a talk about it because someone explained to me how it worked because I needed to work with it. And then I gave like an internal talk about it and I was like, this is really interesting. Maybe I should write an external blog post about it, which will like tell other people about this like interesting thing that we have. Um, and also like solidify my own understanding.
Bridget: Teaching others is a great way to learn stuff better yourself, that’s for sure.
Julia: Yeah.
Bridget: Um, so again, for our listeners who maybe don’t use service discovery, or at least don’t know that they use service discovery, can you give us your 10,000-foot overview? Well, what is it? And aside from like an academic definition, why do you want it?
Julia: [00:17:00] Right. So we have AWS instances. And there are 2 things that AWS instances can do. They could go down and they can come up. You can get new ones and you can lose ones. So losing instances is kind of a problem. You don’t need service discovery to solve the problem of losing instances. So we run, like, all of our API servers live behind load balancers. Those load balancers will just be like, hey, that service is down. I’m not going to send any more requests to that machine. Even if you lose machines, as long as you have something like a load balancer, and if you’re doing web—
Bridget: If you need to route traffic.
Julia: Yeah. If you need to route traffic, then you can have a health check and you can do that.
Bridget: Because there are worker-type things that could run some agent or run a worker and just go harvest things off a queue and process them and not need load balancing. So like there’s, there’s the ability of some services to not need to get registered somewhere, but like why would we want services to get, or, you know, nodes that are providing a service to get registered somewhere? Like what kind of use cases does that help with?
Julia: [00:18:15] Right. So if you’re adding new nodes, then you need to, you need to be able to register them somehow. Right. And so before we had the system, we basically ran a manual, like We would use Puppet and we would Puppet some machine and it would register the nodes and that would kind of work. But it was pretty slow and very toilsome, right? There was a person, you would have to, as a human, go run Puppet.
Bridget: And for people who are using configuration management as part of their service discovery, The point of that would be, as part of your initial first run, go register yourself somewhere?
Julia: Well, it could be that. I think what we actually did was we would puppet, create a configuration file on the load balancer saying, okay, here’s the list of nodes.
Bridget: [00:19:18] Okay.
Julia: Yeah.
Bridget: So this wasn’t Amazon’s ELB. This was something you were doing with HAProxy or something? Yeah, this is something we were doing with HAProxy. As one does.
Julia: Yeah. Yeah. Um, but yeah, you could also use an ELB and have your, um, and like, that’s a totally reasonable thing to do. Like, it’s not, uh, it’s not obvious that that’s worse than what we do, right?
Bridget: Like, well, I mean, yes and no, right? So this, this kind of takes us to the, does it make more sense to, um, tell the nodes through, you know, auto scaling groups or, you know, launch configs or whatever that they’re behind this ELB and that solves everything. Or does it make sense in some cases for the nodes to be making themselves available? Like there’s arguments to be made, I would say, especially in the monitoring space for there being real value in the nodes checking in when they’re healthy. Like, can you address that a little bit? Like the difference between polling and like checking in? I know that’s like way off topic of what we were going to talk about. I’m probably not phrasing this well, but like imagine It’s possible. Like, I’ve seen people— I think Etsy does a bunch of stuff with Chef where they register hosts with Nagios, like, after it’s done a Chef run. And then I guess if the host is gone, like, you know, Chef cleans it up or whatever. There’s a bunch of plugins you can use to do that. Um, but that’s a little bit different than a host, like, registering itself with a console saying it’s available and then removing itself. Because like if you’re registering yourself just with configuration management, like what kind of constant updates and health checks are there?
Julia: [00:20:59] Right. Yeah. So I think of registering yourself as being like very different from health checks. So like we, like our load balancer does health checks and like Consul will also do health checks, but I don’t think of those as being very important or as important.
Bridget: Okay.
Julia: Because like If the node, especially, I mean, as we have not explained, but the blog post says, we don’t actually get updates from Consul very often. We only get them like every minute. So like in the time when like a node said, hey, I’m up, to like when you’re actually sending it a request, it could be like 30 seconds later and it could have gone down, right? So we do a lot of health checking separately from Consul.
Bridget: That makes sense. Just on like on a routing layer?
Julia: Yeah, exactly.
Bridget: Okay.
Julia: Yeah, like in the load balancer.
Bridget: Okay, so I feel like we jumped, we, I jumped us way ahead. So let’s just go back to how did you decide that you had a problem that you thought Consul would solve? And like, what was that problem?
Julia: [00:22:03] Oh, so the problem was that registering new hosts was too much work and we wanted it to happen like continuously and automatically.
Bridget: And not have manual intervention.
Julia: Yeah, not have manual intervention.
Bridget: Okay. So like, how does Consul help with that?
Julia: Right. So Consul advertises itself as a service discovery system. And it lets you have an agent on every host. So you’re like, so you have this Consul agent running and then it reports, hey, I’m a server. Hello. I’m running this thing on port 80 to the Consul server. And then there’s like a central Consul. There’s actually several Consul servers. And then they have a database of like everything that’s running right now. And then you can query that database to get information about where all your API servers are, for example.
Bridget: I haven’t run Consul in production myself. I’ve played with it a bit. And it kind of seems like there are a number of Consul servers and then there’s this whole gossip protocol and like What, if any, of that actually affects how you use it in real life?
Julia: [00:23:09] Right. So one interesting thing about Consul is that it’s a strongly consistent system like we talked about before, which means that— so there are several servers, they all kind of maintain consensus. And this means that you have this guarantee that no matter where you query, you’ll always kind of get a totally correct response. About which servers are up. It turns out that this is not a very important property to have. Really? Or it wasn’t an important property for us because I would like to sort of know which servers are up. But if I’m like missing a couple or if there are a couple of extra servers, it’s not that big of a deal because our load balancers Like if you’re telling the load balancer, like, hey, here are the servers, then the load balancer is in charge of checking, of like double-checking that anyway.
Bridget: Right. So the load balancer is going to do some sort of health check, maybe have some kind of connection stickiness or other independent from Consul ways that it’s deciding that this is an okay place to send traffic.
Julia: [00:24:18] Yeah. So it turns out that for service discovery, a lot of the time you don’t really care if your results are exactly right. You just want to be mostly right.
Bridget: This is, of course, for— we’re not talking about a data store where maybe you have not quite enough replication. There certainly are scenarios where you would care a lot about that one and, oh, why did we not make sure we have better replication there? But this sounds like a lot of API endpoints or whatever where it doesn’t really matter which one you hear from as long as you hear from something.
Julia: If you’re like, oh, I have these 96 instead of those 97, 7, then you’re like, well, it’s kind of the same thing, um, as long as you know that you’re not too wrong, right?
Bridget: Okay, so it sounds like there were a couple of ways that you could have implemented that. Uh, can you, can you go into some detail, a little bit of an overview of like the stuff you talked about in the blog post about how this solution is working out for you? Like, what parts of it do you like? Which parts of it are still an unsolved problem?
Julia: [00:25:20] So we started out by querying Consul, like, when— by being like, hey Consul, which servers are up? And it would be like, these ones. And we’d be like, great. It turns out that this didn’t work that well because the Consul was like too consistent. So sometimes it would be like, I’m having a leader election. This is a disaster. You cannot get servers. And we were like, we would like servers. I don’t care. Just any servers, not— they don’t have to be the right servers. And it was like, I’m having a leader election. And like, we had fallbacks and it wasn’t like a disaster, but it wasn’t really a good state to be in that like our service discovery system became occasionally unavailable, right? So we decided that we wanted to have a system that was available all the time, but that was not as consistent because we didn’t care about that. It turned out.
Bridget: What changes did you have to make to make that possible?
Julia: What we did is we put files. What do we do? Consul comes with this thing called Consul template, which will query Consul and create a configuration file. We use HAProxy to do load balancing, so we generate an HAProxy configuration file every minute being like, okay, these are the servers that are up right now. Then that configuration file won’t go away if Consul goes away. And the worst thing that can happen is we have kind of an old set of servers, which isn’t that big of a deal.
Bridget: [00:26:49] So, and does that— I can’t recall off the top of my head if HAProxy does like a live reload or like how does that work?
Julia: Yeah, so it does a graceful reload where basically it’ll fork and then the old process will handle all the old connections and then the new one will pick up new connections.
Bridget: Oh, okay, cool. So then you don’t— hopefully you don’t end up with connections being interrupted every time this is happening. Right. Well, I mean, Presumably your, you know, NGINX or whatever connections wouldn’t be affected, but—
Julia: Yeah, no, but yeah, it does. I think that there are some, like a small amount of edge cases. There’s a blog post from Yelp which talks about how like it can cause some small problems, but they deal with a lot more traffic than we do. Like at the kind of payment scale, it’s not a problem for us.
Bridget: Yeah, I kind of feel like if, if you had payment traffic that was coming in at the same, uh, load that presumably Yelp has stuff coming in, you might be asking yourself other questions like, what’s going on? This is exciting.
Julia: [00:27:55] Yeah, like, what do I do with this, like, flood of money?
Bridget: Yeah, exactly. Um, okay, so, and you wrote this blog post for Stripe, but you also do a lot of blogging yourself, um, and we’ll put the URL in the show notes, but if you want to just tell our listeners I started blogging.
Julia: I was at this retreat for programmers called the Recurse Center 3 years ago now, and I decided to write a blog post every day about what I was learning. I think I joked to my partner that it was my media strategy to get a job afterwards. Did it work? It did work. It was very effective. I also just thought it was cool that I was learning all these things and I wanted to write about it. Um, and I, I took this approach then, uh, which I still try to take now, where I was just like, I need to write something every day. I’m just gonna say what I learned today. If people think it’s interesting, they’ll read it. If they don’t think it’s interesting, they won’t read it. I don’t care. Like, it’s not gonna be perfect.
Bridget: [00:28:58] And then the not gonna be perfect thing, I think, is a really good attitude. Like, when One thing I really appreciate, that whole spirit of discovery in your blog posts, is that you’re okay with people realizing that, oh my God, you don’t know absolutely everything about every topic on the entire planet. I feel like a lot of people walk around wanting to show what an expert they are in whatever area, but not really talk about the things that they don’t know. And like, it’s hard sometimes, I think, for people to admit they don’t know something, but Admitting you don’t know something is a really important step in learning it.
Julia: Yeah. And it’s also important at work. I have this service discovery cluster, which is my job to work on. It’s my job to make the system work. And so, but when I joined my team, I didn’t know how it worked. And so I had to be like, well, I don’t know how this works. And now I do know how it works, and I can, like, work on it responsibly, right? And make something that will work really well for our customers.
Bridget: [00:30:04] And that’s, I think that’s another, like, teasing out how you both taught yourself and interacted with your team to learn is particularly interesting because you mentioned Montreal. And I don’t know if people know where Stripe, a lot of Stripe employees actually sit, but maybe go into a little bit little bit of detail about your remote situation?
Julia: Yeah, I live in Montreal. Stripe is in San Francisco. Most of my team right now is remote. And I think like for the entire time that I’ve worked at Stripe, I’ve worked on teams which were mostly remote.
Bridget: And how long have you been there now?
Julia: Almost 3 years.
Bridget: Time flies.
Julia: Time does fly.
Bridget: I feel like one of the reasons that people say that remote is hard, or they have trouble with it, or they have a hard time supporting it on their team, is this idea of onboarding new people, teaching them things, helping people with questions. How do you and Stripe approach that in terms of giving you ways to discover things on your own and holding your hand through discovering things?
Julia: [00:31:15] So, I’m pretty aggressive with asking people questions. I remember when I started, I would join this data infrastructure team. Where I needed to work with like Hadoop and like, I’d never used Hadoop before. I had no idea. I was like, what is Hadoop? Like, I don’t know what’s happening.
Bridget: And you and everyone else who ever touches Hadoop for the first time, right? So many Java stack traces, so much sadness.
Julia: So much sadness. So I remember on the plane back from San Francisco, I was like interrogating people. I was like, what is HBase? What is Spark?
Bridget: Scalding?
Julia: What is yarn? Like, what? Like, I just like went down like every noun that I didn’t understand, which was all of them, and got them to explain everything to me. And I’ve definitely like dealt with this by like being like extremely proactive. When I joined my new team, my manager at the time was like, so often I warn people that they need to be like kind of proactive with like asking questions and like, like no one’s going to tell you how everything works and you need like go ask for yourself. He was like, but I’m not worried about you. You’re gonna be okay.
Bridget: [00:32:25] That’s so awesome. Um, but so, and you said your team is mostly remote, so like what kind of techniques or processes or tools do you use to ask and answer questions for each other?
Julia: I talk on Slack a lot. Um, I sometimes schedule, like if I want to know something more in depth, I’ll schedule like a Google Hangout. I also sometimes use the technique of going to San Francisco, spending some time with people there.
Bridget: But yeah, we all do that.
Julia: My colleague Nelson, who is the best, was like, did a lot of the initial work setting up the cluster. So I at some point made like a list of like a whole bunch of questions I had for him. And I was like, here are all of my questions. And then, like, we went through everything.
Bridget: I feel like having the willingness to ask those questions also helps the person who set it up. And realistically, you’ve set clusters and things up yourself too, where you don’t really remember absolutely. Once you get to the end of it and it works, going back and remembering every false start and every piece that you did get working the way you wanted is sometimes forensic archaeology. Like getting somebody coming in with an informed set of questions so that you can kind of describe the current working state of the system, I think is really nice.
Julia: [00:33:45] Yeah. And I think it’s really like you could be a really good partner in like the handing off of a system because it really sucks if you set something up and then you’re in charge of it forever.
Bridget: Like, yeah, the side effect that goes along with being territorial is good luck ever having new projects or getting promoted.
Julia: Yeah. And I’ve seen a few people do really amazing jobs of coming into a system and being like, someone else set up the system, I don’t know how it works. And then going from there to being like, I am the primary maintainer of the system, I know everything about how it works, and really becoming the expert. And I think having examples of that is really important.
Bridget: Yeah, I really like that. I think, uh, both writing externally facing blog posts and personal blog posts about tech, um, are pretty good ways for you to both demonstrate your knowledge— certainly doesn’t help for any future, you know, employment conversations— but it also helps inform people around you, whether it’s the wider internet or your coworkers or whatever. Um, and you don’t just write the blog posts either. Like, talk a little bit about the zines and these comics, because this is like kind of unusual and Really exciting.
Julia: [00:35:01] Yeah. So a zine is like, it’s short for fanzine and it’s basically like a little tiny magazine about like something that you love. So in 2014, I was giving a talk at PyCon about debugging tools for Linux, basically. And I was, I think I’d watched this like Anyway, I’d watched this movie about like Riot Grrrl and like the ’90s and fanzines anyway. And I was kind of excited about like independent publication. And so I was like, I know what I’ll do. Because I would always give these talks and then people would be like, what do I read after your talk? And I would try to give them links and then, but I could tell that they kind of, they weren’t reading the links. And I was like, well, how do I get people to like read the stuff after my talk? So what I decided to do was to like publish like a physical thing that I would hand out to everyone in my talk. Like a handout. And then I was like, well, I’ll just make it like a fanzine that’s like something like about what I love. So I wrote the zine about Estrace, which is this tool that I really love.
Bridget: [00:36:09] They had copies at DevOps Days New York. It was adorable.
Julia: That made me really happy. And stickers. Stickers.
Bridget: Yeah.
Julia: Yeah. And I felt like that worked really well because like if you put something into people’s hands and you’re like, this is the stuff that I want you to know, then they can go read it like on the bus or whatever, right? You can kind of compete better for their attention. Um, and also it was really fun to make. Um, so I made another, uh, zine recently in September about like a bunch of Linux debugging tools that I love. Um, and I think that one went really well.
Bridget: Oh, that, that’s awesome. And then like talk a little bit about, um, This idea of comics, like putting stuff in, whether it’s in, I guess, slides for a conference talk or in a blog post, like, what kind of difference or value is there with making something more of a comic art sort of endeavor instead of, like, another paragraph or bullet points or whatever of text?
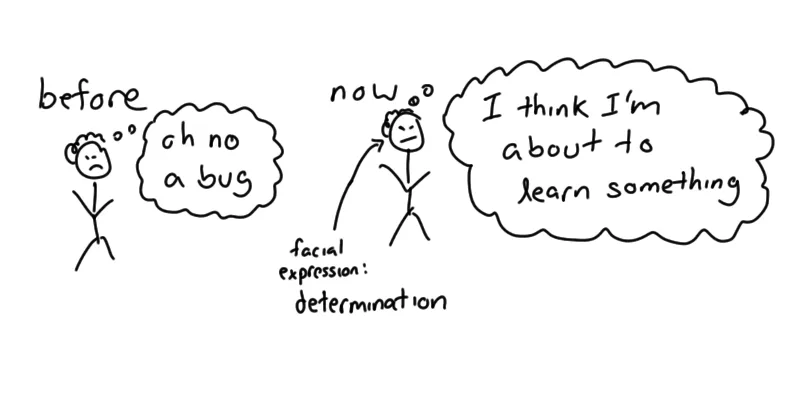
Julia: [00:37:13] I think there are a few reasons this works well. I wrote this blog post about service discovery, I thought it was like a pretty good blog post and that it was explained pretty well. And then someone was like, Julia, you should put a cute drawing at the top. And I was like, should I? And then I was getting on a 6-hour plane ride, so what better time to draw something, right? And then when I got off the plane, I sent it back to the person and I was like, well, here’s what I made. And he was like, this is amazing. I can understand everything in your post so much easier, more easily from just looking at this drawing, right? So, and of course, like, the drawing doesn’t explain everything about how service discovery works at Stripe, but they can be like a really good summarization tool where you’re just like, these are the main concepts. I also did this recently. So when you set up a new, like, web service at Stripe, we have this, like, long document explaining how to do it, which is like 8 steps. And I just wrote some new documentation. And when I sent out an email to all the developers about the new documentation that I wrote, I also drew a comic being like, these are the 8 steps. That’s so awesome. In comic form, just to help people see this is the big picture. And it’s kind of cute, but I think it’s more important that it is a good summary of what all the steps are. And you can kind of see it at a glance and understand the main ideas. The other reason that I do it is I spend a lot of time on Twitter and like it can be kind of hard to communicate stuff on Twitter. And I think a lot of people have noticed that if you post images on Twitter, you can communicate a lot more. So I’ve been making these like small comics that I post on Twitter where I’m like, oh, here’s like /proc, right?
Bridget: [00:39:00] I love the /proc one. It’s so cute.
Julia: Yeah, I love it. I was, I was actually really surprised by it because I think I wrote it. I was like, I don’t know what I’m going to write about. And I was like, I’ll just write about /proc. I’m really tired. And then I woke up and I was like, oh, people really didn’t know about /proc, did they? Okay, cool.
Bridget: Well, I think this is, this is kind of, you know, it’s related to the Systems We Love Day that they’re going to be having in San Francisco soon. Like this idea that There’s a lot of things, whether it’s inodes, I know you were recently talking about, or /proc or whatever, that we interact with these things every day, but how much have we actually paid attention to them? And like, they’re pretty significant. Like, tell us about inodes since I know you just did a really cool post about inodes.
Julia: I started at inodes. I wrote about inodes because I was like, what actually is an inode? Like, and so I decided to chart it down. It turns out that every file has an inode and the inode, the inodes live in like a huge array on my hard drive and they’re numbered like 1, 2, 3, 4, 5, 6, 7, 8, 9, 10. And they’re just in like this flat array. And then inode like 27391 represents some kind of file and it’s like, here’s where that file lives on disk. Like here’s where like the data blocks are. And like, here’s who owns the file. And I was like, oh, that’s not that complicated.
Bridget: [00:40:28] It’s, it’s not that complicated, but it’s also a place that you can run into bizarre failure conditions.
Julia: That’s right.
Bridget: It’s possible to run out of inodes, for example.
Julia: It is possible to run out of inodes. That’s actually why I drew the comic, is because once I ran out of inodes and I was like, I did not know you could run out of inodes. And I was like, I will tell the world that you can run out of inodes.
Bridget: I remember that a long time ago there was a joke Usenet newsgroup called alt/why-do-unix-systems-have-so-few-inodes. I don’t think anyone ever actually posted in it. It was more somebody made that newsgroup because they had one of those days where the answer was, oh, I ran out of inodes. You gotta be kidding me.
Julia: Yeah, it’s such an upsetting thing.
Bridget: Totally.
Julia: But I feel like there are just so many of these things that you learn over the course of your career where everyone has a day, or not everyone, but many people have a day, which is the day that they learn that you can run out of iNotes.
Bridget: And then they’re like, come on.
Julia: [00:41:29] And like, maybe it’s better for that day to be like when you read an adorable comic on Twitter as opposed to spend a bunch of time troubleshooting. Yeah. And then you can be like, oh, this is like in that comic. Maybe I can deal with the situation like more quickly now.
Bridget: Nice.
Julia: I like that.
Bridget: So You mentioned containers earlier, and I know that you wrote a couple of blog posts about that. Does that mean that you are using containers at Stripe, or is this more you’re interested in learning about them? Like, I know people get excited about containers and the orchestrating thereof, so I’d love to hear more about your ideas there.
Julia: Yeah, um, so the reason I’m interested in containers, um, is that I’m interested in making our infrastructure easier to use for Stripe developers. I think the way to do that is going to have to be to use containers. I’m not fundamentally weirdly that interested in containers. I think when people talk about Kubernetes, my normal reaction is to be like, oh no, you’re talking about containers again. There’s so much hype around it and I often find it really frustrating. Because there’s like a lot to like, like slog through. Right.
Bridget: [00:42:51] Well, and the hype is, I mean, it’s all kind of nonsense. Like, where’s the practical applications of where you see this stuff can make your work easier, your coworkers’ work easier?
Julia: So the thing I’m, I think, most excited about right now is we have a lot of different instances that are configured in a lot of different ways. And maintaining all of the different configuration for all the different kinds of instances is a lot of work. It’s very stressful, or it’s a lot of work for Stripe developers. Someone was setting up a new service this week and they were going through all the steps and I was like, I’m sorry, this is a lot of work, right? To set up a new type of instance. And so Like the promise of Kubernetes is that you can just like have like kind of a uniform infrastructure, right? Where you configure every box the same way and then you just like run things on those boxes. And I think that promise is really compelling. It makes it a lot easier to run a lot of machines and like kind of isolating, like putting everything inside a container and having that boundary where you’re like all of your special Snowflake magical configuration lives inside your container. I think it’s a really compelling user experience promise.
Bridget: [00:44:13] Yeah, I mean, and there’s a lot to be said about where exactly the boundaries are and what you do with everything in terms of inputs to and outputs from the containers. Like your individual, you know, cgroup and namespace processes, like still have logs. The logs go somewhere. So there’s a lot to unpack there. But I’m actually excited now because I know that as you implement stuff like that at Stripe, you’re going to write amazing blog posts.
Julia: Yeah. I think one thing that’s kind of difficult about containers is that they’ve been very successful on the desktop as a developer tool where you’re like, okay, I want to develop I want to set up my developer environment, and I’m going to use a container to do that. And that’s been, I think, incredibly successful. But I think sometimes people conflate that success with containers in production, where I think the story is a lot less clear, and it’s a lot less obvious what to do.
Bridget: [00:45:17] Yeah, and I couldn’t agree more. And I mean, I’ve run containers in production, and there are some things that are really great, and there are other things where you chase a lot of bugs. And I mean, like any other software written by humans, there are going to be trade-offs. And in the case of where we were doing it, the trade-offs made sense for us. But I think that starting from, we would like some containers, or we would like to orchestrate some containers, or we would like to drive our utilization to 99%, and then trying to retrofit everything around that kind of stated goal is like, Well, what business problem are you solving?
Julia: Right. Yeah. And I mean, utilization makes sense as a business. Like, I think a lot of people have used containers historically because they’ve been like, well, I have all these computers and if I don’t, like, if my utilization is too low, I won’t be able to make money. Right. Like, sure. I won’t be able to like have a viable business.
Bridget: But like 99% is a pretty unrealistic utilization.
Julia: [00:46:18] Oh yeah. 99% is too high. I mean, but it’s like, you could be like, I’m at 20% and I want to be at like, 80%, and I think containers will help get me there.
Bridget: Oh yeah, absolutely. Well, and you also mentioned like the overhead for developers working with a new system. You could imagine having a little bit less in the way of context switching overhead if developers are moving from working on one subsystem to another, but there’s a lot of the underlying infrastructure for them that’s the same, so they don’t have to spend so much time with fiddly bits. I think the reason I wanted to just kind of chat with you about discovery is I feel like you have this enthusiasm for learning this stuff that it can’t just be boiled down to, and I have to learn it to do my job and be effective and create stakeholder value. Can you give people ideas or tips as to maybe if they wish they were excited about learning stuff and they haven’t really figured out how to be excited about it lately. What, what would you recommend for people who want to be excited about learning or excited about learning again?
Julia: [00:47:27] I think the way I got more excited about learning things is I went to the Recurse Center.
Bridget: Nice. So in a supportive environment of other people who encourage you to focus on learning.
Julia: Yeah. And they’re like, I mean, I had like 12 weeks to like learn whatever I wanted. And then I was like, oh man, there are all these things to learn that I didn’t even realize that I could learn. Right. Which was really exciting. And then I think that kind of like affected me permanently. And now I’m stuck learning things all the time.
Bridget: I mean, I think that’s great. But you’re also— you chose an employer that’s a place that lets you stretch and learn stuff.
Julia: I guess that’s true. I didn’t think about that.
Bridget: Because if you imagine it— oh, go ahead.
Julia: Like, I feel like I can’t. I find it hard to imagine it being otherwise.
Bridget: I think there are places where incentives are structured such that you just have to ship, ship, ship according to processes and procedures somebody came up with. And there’s no time to explore this thing that you’re interested in over there because we just have to get this thing out the door. Like there are places with those sort of pressures.
Julia: [00:48:37] Yeah. Like I feel like just in order to like do my job, I need to learn so much. Yeah. Because it’ll be like, Julia, Can you like make everything about how we like run services easier? And I’m like, well, okay. Like there are like many several things I do not know.
Bridget: Nice. Well, and that is a really important factor too. Like we talked about that a little bit earlier, but being willing to be vulnerable, be willing to, being willing to ask other people questions. Like if somebody feels discomfort with that, what would you recommend?
Julia: So I think my coworkers are extremely supportive about it. I don’t think anyone has ever been like, Julia, that’s kind of a dumb question. And I think if you’re in an environment where people are not receptive to being asked questions, it’s very hard to do. One thing I think I realized is that it’s actually very hard to ask good questions. And I think I’ve gotten a lot better at it. So I think one of my favorite compliments I ever got is one of my coworkers was like, Julia, you always ask such good questions. I always really want to take them seriously and give you a really good answer. And I was like, oh, that’s wonderful.
Bridget: [00:49:58] I really like that.
Julia: But I mean, it really is like asking questions really is like a skill. And like asking the right questions really is a skill, right? Like sometimes I’ll just be like, what? Like, I don’t understand. Like, I don’t understand is like not a very good question, right? Or like, how does this work? Is like not always that good of a question.
Bridget: How would you suggest formulating a good question if somebody wants to discover how something at their job works?
Julia: So one thing that I do a lot is I try to understand how it works a little bit on my own. And then I’ll describe to someone how I think it works. I’ll be like, okay, so I understood this, this, and this. And then normally I’ll be wrong about some aspect of it, right? Or they’ll be like, you left out this extremely important thing. And I’m like, oh, that’s because I didn’t know it, right? Or they’ll be like, you’re almost totally right except for this one part which was wrong. And so I think asking someone to check your understanding Um, can be helpful. And like, to be able to do that, you obviously need to like know like some amount already, or start by reading some amount. Yeah, or start by reading something.
Bridget: [00:51:05] Read the Wikipedia entry, read the man page. If things in it don’t make sense, keep looking, and then maybe try to outline what you think does make sense, and then talk to somebody who probably understands it better than you do.
Julia: I wrote a blog post about this called Asking Questions Is Hard, uh, but worth it.
Bridget: I’ve read a bunch of your blog posts, but I think I might have missed that one. So, hey, excellent. After this, I have something new to go read.
Julia: I have an infinite number of blog posts. Well, what was I going to say? Oh, yeah. I think the other thing that’s helped me is I’ve developed this hopefully unshakable confidence that I can kind of figure anything out. So it’s like if I don’t understand something, it’s either because, uh, I haven’t learned it yet. Like, it’s like either— like, there are things that I don’t understand which I’m not going to learn because I don’t think that they’re like important enough for me to learn. Um, and there are things that I don’t understand yet just because like I haven’t gotten around to it yet. Um, and I just need to like spend the time, right? And I find it a lot easier to think of like, oh, I don’t understand this because I haven’t like taken the time to go learn it. Um, rather than like, I don’t understand this because this is like too hard.
Bridget: [00:52:14] That’s a really good place, I think, to wrap up, to just say, like, there’s not one way to learn things, and there’s not, like, this, you know, manual that I got with my computer science degree, and if somebody got a math degree, well, clearly, they know tons about math, but how will they ever learn distributed systems? Like, that’s clearly nonsense. There’s a lot of different ways to learn this stuff. And it seems like what you’re saying is being open to iterating on your understanding is really key.
Julia: Definitely. And then if you learn one thing at a time, then eventually you come out and you’re like, like, people often like, Julia, you like know all this stuff about like operating systems and like you’re so good at it. And I’m like, that’s because I learned things like one thing at a time. And now it turns out that I know all this stuff.
Bridget: Yeah, that’s, and that’s really important too for people who are, especially people who are trying to maybe redirect their career or take on an exciting new project at work. And then they think like, if just statically other people are the expert in that, I’m currently not. Like if they leave it there, it’s like, well, somebody isn’t gonna necessarily come along and anoint you the expert, but you can probably make yourself the expert or an expert.
Julia: [00:53:32] Yeah, definitely.
Bridget: That’s so great.
Julia: Yeah, but it takes like, like, I think you often have to be like very proactive about like making like, yeah, no one has ever anointed me the expert of anything.
Bridget: Well, and I also think that we can be pretty comfortable knowing we can solve some quantity of production problems about a system and still not understand it deeply down to like the byte-level code. I mean, It’s like, there’s gonna be some amount of understanding that we have and some amount of understanding that we just punt on. Like, that’s probably fine.
Julia: Yeah.
Bridget: Like, it’s— I think it— the people who ask like the Toyota whys or people who try to do root cause analysis, it’s like, okay, root cause is wherever you land when you stop asking why, but there’s always gonna be more stuff down there somewhere.
Julia: I think you can always kind of keep going deeper. I think kind of like the lowest I think I’m comfortable looking is in the Linux kernel code. I think I now think it’s not that unreasonable if you really have a question to be like, okay, what does the Linux kernel have to say about how that works? Right? And that’s not something I do very often, but it turns out it’s totally not impossible at all.
Bridget: [00:54:57] Well, and I think that there’s probably a lot of people who will think, huh, okay, so when I have questions about something that’s a complete mystery to me, but I suspect it might be somewhere down there in the Linux kernel code, I’m gonna ask Julia. So if people are looking for you online, wanted to chat with you on Twitter, read this blog, we’ll put links in the show notes, but where can people find you on the internets?
Julia: On Twitter, I’m Bork with a zero. I also have a blog which is at jvns.ca, which is not the kind of thing that you can say out loud.
Bridget: I mean, you can say it. People might be able to write it down while they’re on like the treadmill or whatever, but they’ll be putting it into their phone looking right now while they’re listening. Um, okay, cool. So I think we had a, we had a couple of things that we wanted people to read or check out other than your blog, which will definitely be linked here. Uh, so you want to— you told us a little bit about this before. Do you want to kind of tell us why should people read this critique of the CAP theorem?
Julia: [00:56:08] So I think it’s interesting because basically, like, I like this critique of the CAP theorem because, like, the idea that the CAP theorem is, like, not the right tool was, like, very surprising to me. Um, and I like things that are surprising. Like, I was like, what do you mean? The cap theorem is the thing. And he was like, the cap theorem is not the thing. There are other things that might be more useful to you as like someone who is trying to like use, like make practical systems. And I was like, what?
Bridget: So what’s an example of a practical— you were mentioning one earlier, but I want to kind of just wrap up with what’s, what’s the practical system that led you to thinking about this stuff?
Julia: So originally I was thinking about a replicated database where you might like write to a primary, which might be slow, but then you might read from a secondary.
Bridget: Oh, okay.
Julia: And it would be fast. Like a system like that, which I think CAP does not really help you reason about in any way. It’s just like, well, that’s not like linearizable or something. And then it’s like, you should feel bad or something. Like, I don’t know, right?
Bridget: [00:57:19] Like, you’re bad and your database is bad and you should feel bad.
Julia: But of course, that’s a very popular database model, and it’s appropriate for a lot of people. But the CAP theorem, I think, does not help you with it at all, is my understanding.
Bridget: Yeah, yeah. Awesome.
Julia: But then this model maybe speaks to it a little bit more.
Bridget: Cool. We’ll have a link to that in the show notes, which will be, of course, at arresteddevops.com/discovery. Because that’s everything we’re talking about here. Uh, let’s see, I have a couple of checkouts too because I don’t live in Montreal and I live in the United States, and we have all sorts of people wondering how they can help make the world a better place right now. And so there’s a website to match volunteers with skills to orgs that can use those skills called catchafire.org. And I haven’t used it myself, but I’ve definitely been looking at it. And some of it’s kind of prosaic, and some of it’s like, we are helping people and need one of these database things we’ve heard about. It’s like there’s a lot of places where, you know, techies could help there. And also, like, I volunteer teaching English to adult immigrants and refugees at the Minnesota Literacy Council. Ours is at mnliteracy.org. Your local area probably has something like that too, and you might think, well, I have no teaching ability, but generally they run you through a training program that helps. So if you know absolutely anything about how to speak English or possibly do, you know, grade school math, or like if you have an interest in civics— I’ve heard a lot of people are suddenly interested in civics— anything like that, populations in your local area probably could use your help there. Um, okay, so let’s see, upcoming community and event stuff. Uh, you were mentioning Strangely earlier. Do you, do you have any, uh, conference plans pending that you can tell folks about?
Julia: [00:59:21] No.
Bridget: You have some exciting at-home time coming up?
Julia: Unclear.
Bridget: Magic 8-ball says ask again later.
Julia: Yeah, I haven’t yet scheduled my 2017 self to do anything.
Bridget: That sounds delightful. I have not committed to a ton of 2017 stuff. I do have some, but the one thing pending on my horizon that is definitely happening real soon now is I am going to speak at DevOps Days Sydney. So, I am getting on a plane to Australia the day after Thanksgiving. So that should be pretty fun. I’m looking forward to that. I’ve never been to Australia, and there’s— it should be pretty cool. I guess a bunch of people we know are going to be down there for YOW!, but we’re like probably going to be like ships in the night, or I don’t know, airplanes in the night or something, not necessarily intersecting each other. Um, but there are a bunch of DevOps Days still coming up this year, strangely enough, um, mostly in Europe. With a little bit of Brazil and Australia in the mix, and for the rest of 2016. You can see those on devopsdays.org. There are a few CFPs open for next year already on devopsdays.org. A couple of other conferences, ChefConf 2017, the CFP is open till January 18th, and Velocity San Jose. Velocity Santa Clara is actually in San Jose now, So California Velocity for next summer, the CFP is going to close January 10th.
Julia: [01:00:59] So is the Monitorama CFP open yet?
Bridget: Good question. I think it is. Let’s, let’s take a quick look. Monitorama is, of course, delightful. And anyone who has never been there definitely wants to go to Portland because it’s great. So let’s see when that CFP closes. It will be opening soon is what it says. So yes, we’ll put a link to monitorama.com in here as well. Are you going to be in Monitorama this year, are you thinking?
Julia: That’s like the thing on my list that I was going to submit a talk to.
Bridget: Nice. I don’t know, I’m so torn. Like, the problem with submitting to CFPs for me is because I do tech advocacy for work, I also have a lot of work travel that I’m definitely going to have popping up out of nowhere. As time goes by. And so I kind of like to have the conference stuff pretty well plotted out, but with the eventual consistency of CFPs ends up making that sort of problematic. It’s like, I might be busy at this time, I’m gonna wait a month or two to find out. That part ends up being kind of hard when you’re doing a job that already has a lot of travel. So yeah, but that said, like, obviously CFPs are a really, really good way to get— in particular, I think they’re a really good way to get speakers who um, may not have spoken at something before.
[01:02:22] Or— and that, I mean, there’s— we could, we could do another— we are way over time here, so we’re not going to get into that. But you— yeah, we could do an entirely other, um, discussion about how if you put your CFP out there and then you wait and then you close your eyes and shake up all the entries and pull, and then you’re surprised if you find a white guy who works for a vendor. Like, okay, what did you put into the CFP? Like, you’re only gonna have the pool to select from of the people that got, you know, notified about and felt like they could submit to it. So, yeah, but I think that’s one reason we try to talk about CFPs on here, just so that, like, a wider variety of people who maybe haven’t submitted to a conference talk before.
Julia: Yeah. And, like, encouragement is really— like, the first time, the first conference I gave a talk at was PyCon Canada. And I think the guy who runs Montreal Python emailed me and he was like, Julia, you should submit a talk to PyCon Canada. And I was like, oh, I don’t know. Someone already talked about this topic before. I couldn’t possibly. And he was like, that doesn’t matter. And I was like, oh, I guess I’ll submit a talk then. And then I did. And then I gave the talk and everyone loved it and it was amazing. And I was like, oh.
Bridget: [01:03:42] Well, and I would suspect that your talk that you gave with your set of experiences and, you know, probably your awesome drawings and everything else is like a different talk than the other person’s, which was probably a great talk, but it was a different talk than the other person’s, which was a great talk.
Julia: They were both great talks, it turns out.
Bridget: There can be more than one great talk ever. What?
Julia: Yeah.
Bridget: Um, so if people have a CFP coming up that they would like promoted on Arrested DevOps, uh, we have a form at arresteddevops.com. Arresteddevops.com/conf, C-O-N-F, that you can tell us, and we will read about your CFP and your upcoming conference on air. You can head to arresteddevops.com/discovery for this episode’s show notes, and the site also has our newsletter, merchandise, Patreon. I don’t even know if that’s how you pronounce that, so I’m not sure. But all the Arrested DevOps stuff you could ever want. And you can visit arresteddevops.com/itunes and leave us a review in the iTunes store if you want to help other people find the podcast. So, thank you so much, Julia, for being on the podcast. This was super fun.
Julia: [01:04:48] Thank you so much for having me. I’m really delighted that I got to come talk to you.
Bridget: This is so great. This is literally, like, the first time Julia and I have ever talked that’s not on Twitter. So, it’s like, hooray! That means we have to hang out at a conference sometime in 2017. Fact.
Julia: True fact.
Bridget: All right, so I’m Bridget at Bridget Kromhout. We’re Arrested DevOps, and remember, there’s always DevOps in the banana stand.